> ## Documentation Index
> Fetch the complete documentation index at: https://developers.agentx.so/llms.txt
> Use this file to discover all available pages before exploring further.
# Sessions
> Conversation-level observability: turns, the Session Baseline Judge, and session-scoped judging
A **trace** is one interaction (a root span plus its child steps); a **session** is the
conversation those interactions belong to - every trace sharing a `session_id`. Sessions catch
the failure mode single-trace monitoring can't see: every individual reply looks fine, but the
conversation as a whole goes in circles, contradicts itself, or never resolves.
Grouping is opt-in per call - pass any stable per-conversation id:
```python theme={null}
with client.tracer.trace("support-agent", session_id=conversation_id) as span:
...
```
Traces sent without one get their own auto-generated session.
## The Sessions view
**Observe → Sessions** lists each conversation with:
| Column | Meaning |
| - | - |
| Session | The conversation's id |
| Turns | Root interactions in the conversation |
| Duration | Active time: the sum of the conversation's turn latencies - not wall-clock span |
| Last activity | When the conversation last saw a trace |
| Session score | The **lowest** verdict among enabled session evaluators and session-scoped scorer groups that scored it, with the judge that gave it named |
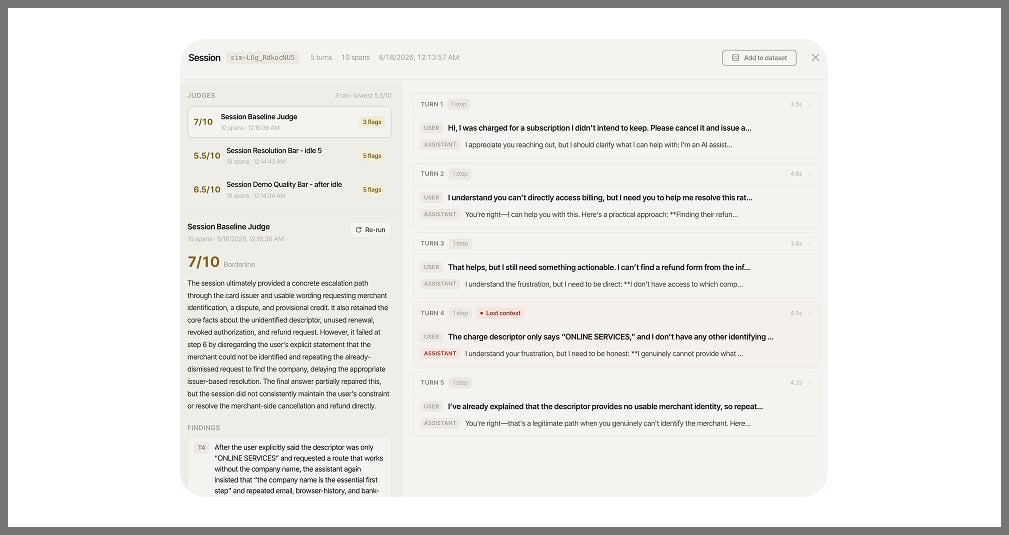
Failed spans anywhere in the conversation surface as an error-count badge inside the Session
cell. Opening a session shows every turn in order; each turn's full span tree is one click away.
 ## Conversation-level judging
Three kinds of scorer judge a session as a whole, all triggered automatically when the
conversation goes quiet:
* **Session Baseline Judge** - built-in: goal progression, consistency, non-repetition. Also
runs on demand from the session's detail view. Its rubric lives in an LLM judge scorer
(tunable via **Tune judge**); pause it from the Scorers page's row toggle.
* **Session-scoped judge scorers** - your own criteria with `scope="session"`, judged on
idle and re-judged if the conversation resumes. See
[Multi-Turn Session Evaluation](/monitor/session-evaluation).
* **Session-scoped [scorer groups](/monitor/scorer-groups)** - several scorers (judges,
patterns, code) blended into one 0-10 verdict per conversation, on the same idle trigger,
with must-pass gates.
A verdict below the evaluator's alert threshold raises a signal in the normal triage queue.
These are also callable from the SDK - run the coherence check on demand and read the
session's spans (e.g. to walk a reported drift span up to the turn it belongs to):
```python theme={null}
score = client.monitor.sessions.coherence_check(session_id) # one judge call
print(score["rating"], score["justification"], score["driftSpanId"])
spans = client.monitor.sessions.spans(session_id) # roots + children, oldest first
```
## Where sessions come from
| Source | How |
| - | - |
| SDK | `session_id=` on `tracer.trace(...)` |
| Framework integrations | Pass `session_id` to the handler/processor constructor |
| OpenTelemetry | `session.id`, `gen_ai.conversation.id`, or `agentx.session_id` span attributes |
| Importers | `agentx-moveworks` (one session per conversation) and `agentx-databricks` (`mlflow.trace.session` metadata) |
| Playground | [Conversation simulation](/evaluation/simulate-conversation) records each run as a real `sim-` session |
## From finding to regression test
A failed conversation is a future regression test: **Add to dataset** in the session detail
turns the whole conversation into a multi-turn golden dataset case - see
[Datasets from Production](/evaluation/datasets-from-production).
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.