- Which high-traffic topics have no test behind them? (the coverage table and map)
- Is this specific request already tested? (the probe)
- Which of my cases test something nobody asks? (cases off the map)
Prerequisites
- Topics classification on (Platform Settings → Monitoring defaults). Coverage is measured against the topics Monitor derives from real traffic, so an install with nothing classified shows an empty state, not zeroes. See Topics.
OPENAI_API_KEYfor embeddings. Without one the table still works but runs in a labelled Approximate mode: coverage falls back to counting cases against a per-topic target instead of measuring depth, and off-map detection is disabled (lexical matching cannot prove a case matches nothing). The map needs embeddings on both sides and has no lexical fallback.- At least one dataset with cases, and for the map at least 10 embedded points across production traffic and dataset cases combined.
The coverage map
The Map tab is the fastest way to see the answer. It draws production traffic and your dataset cases in one picture: a joint UMAP projection in question space (a trace’s input-only embedding against a case’s query-only embedding), so an identical question from both sources lands in the same spot. Points are colored by source, and a translucent density cloud glows around them in the source’s color, so the clouds appear only where questions actually cluster. Use the source chips at the top of the map (Both / Production / Datasets) to read it in three passes.1. What your dataset covers
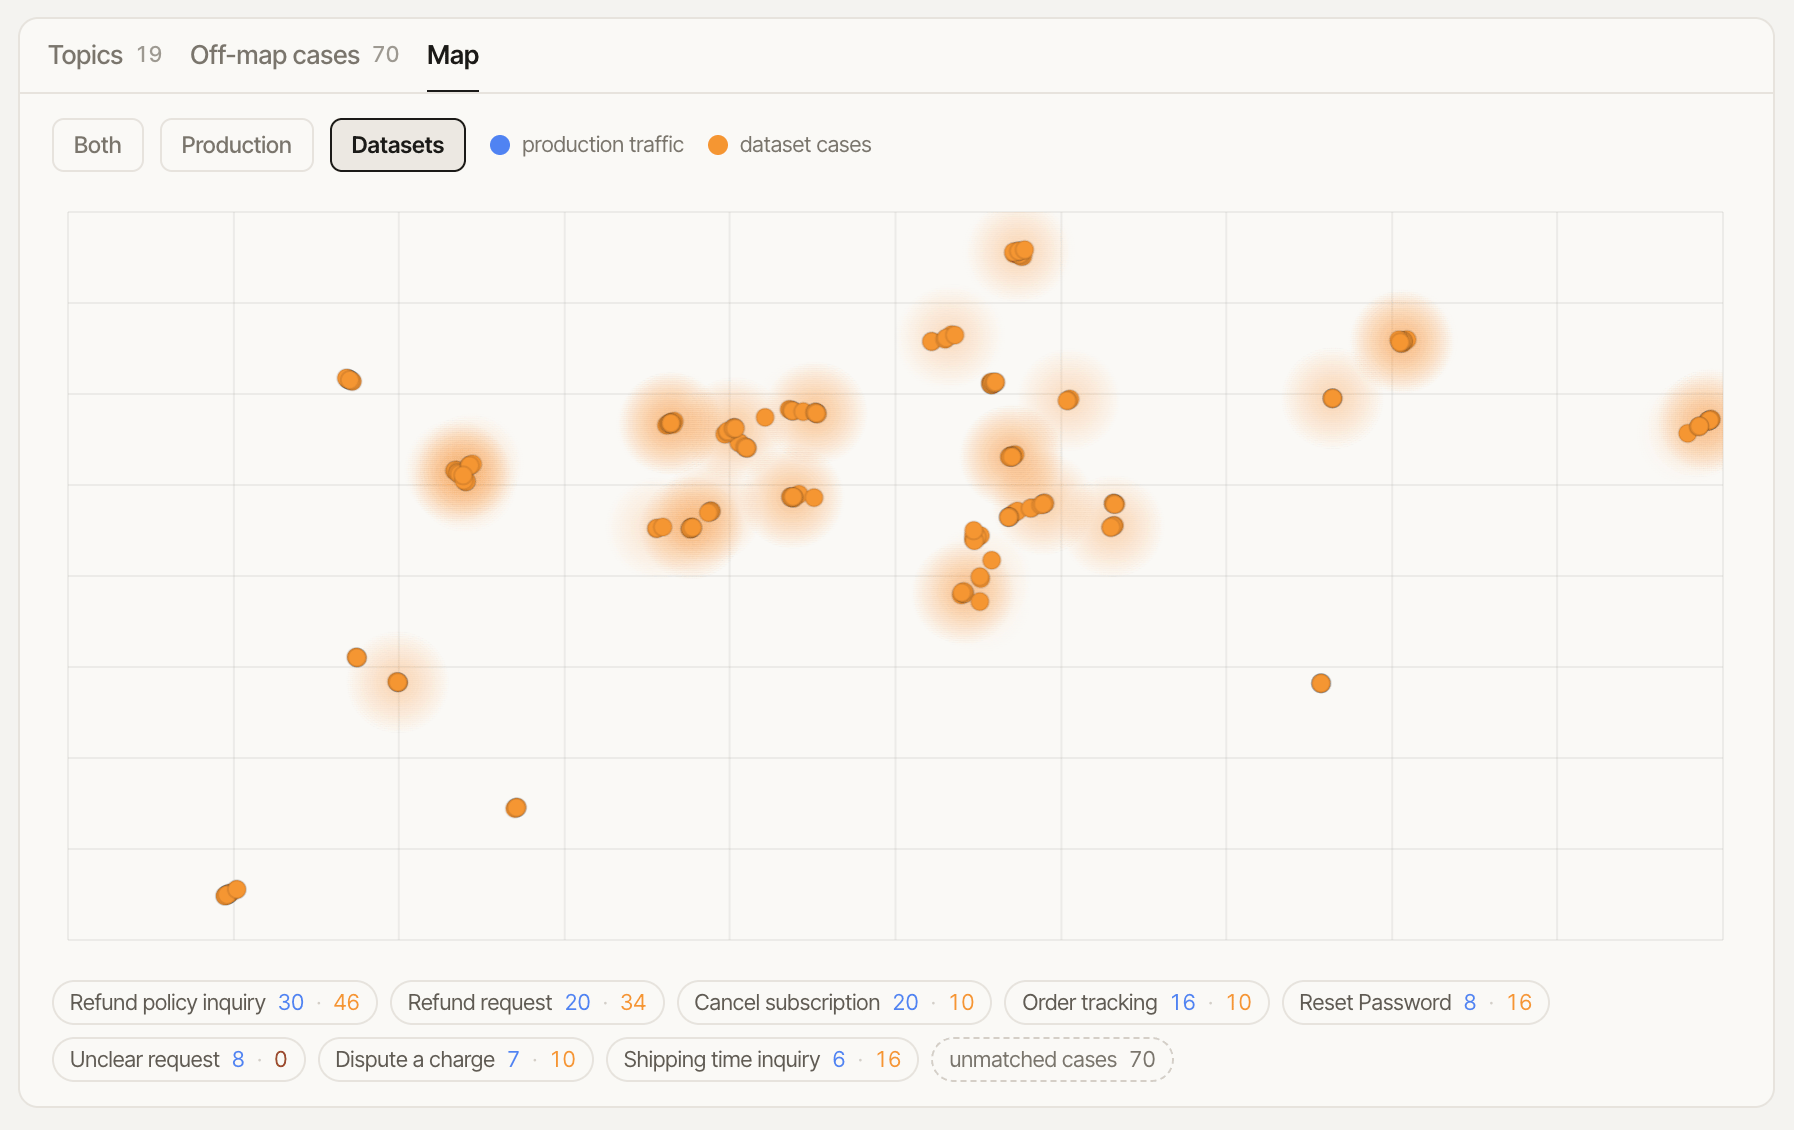
Source chip: Datasets. The orange cloud is the shape of your test suite - where your cases cluster in question space.
2. What production actually asks
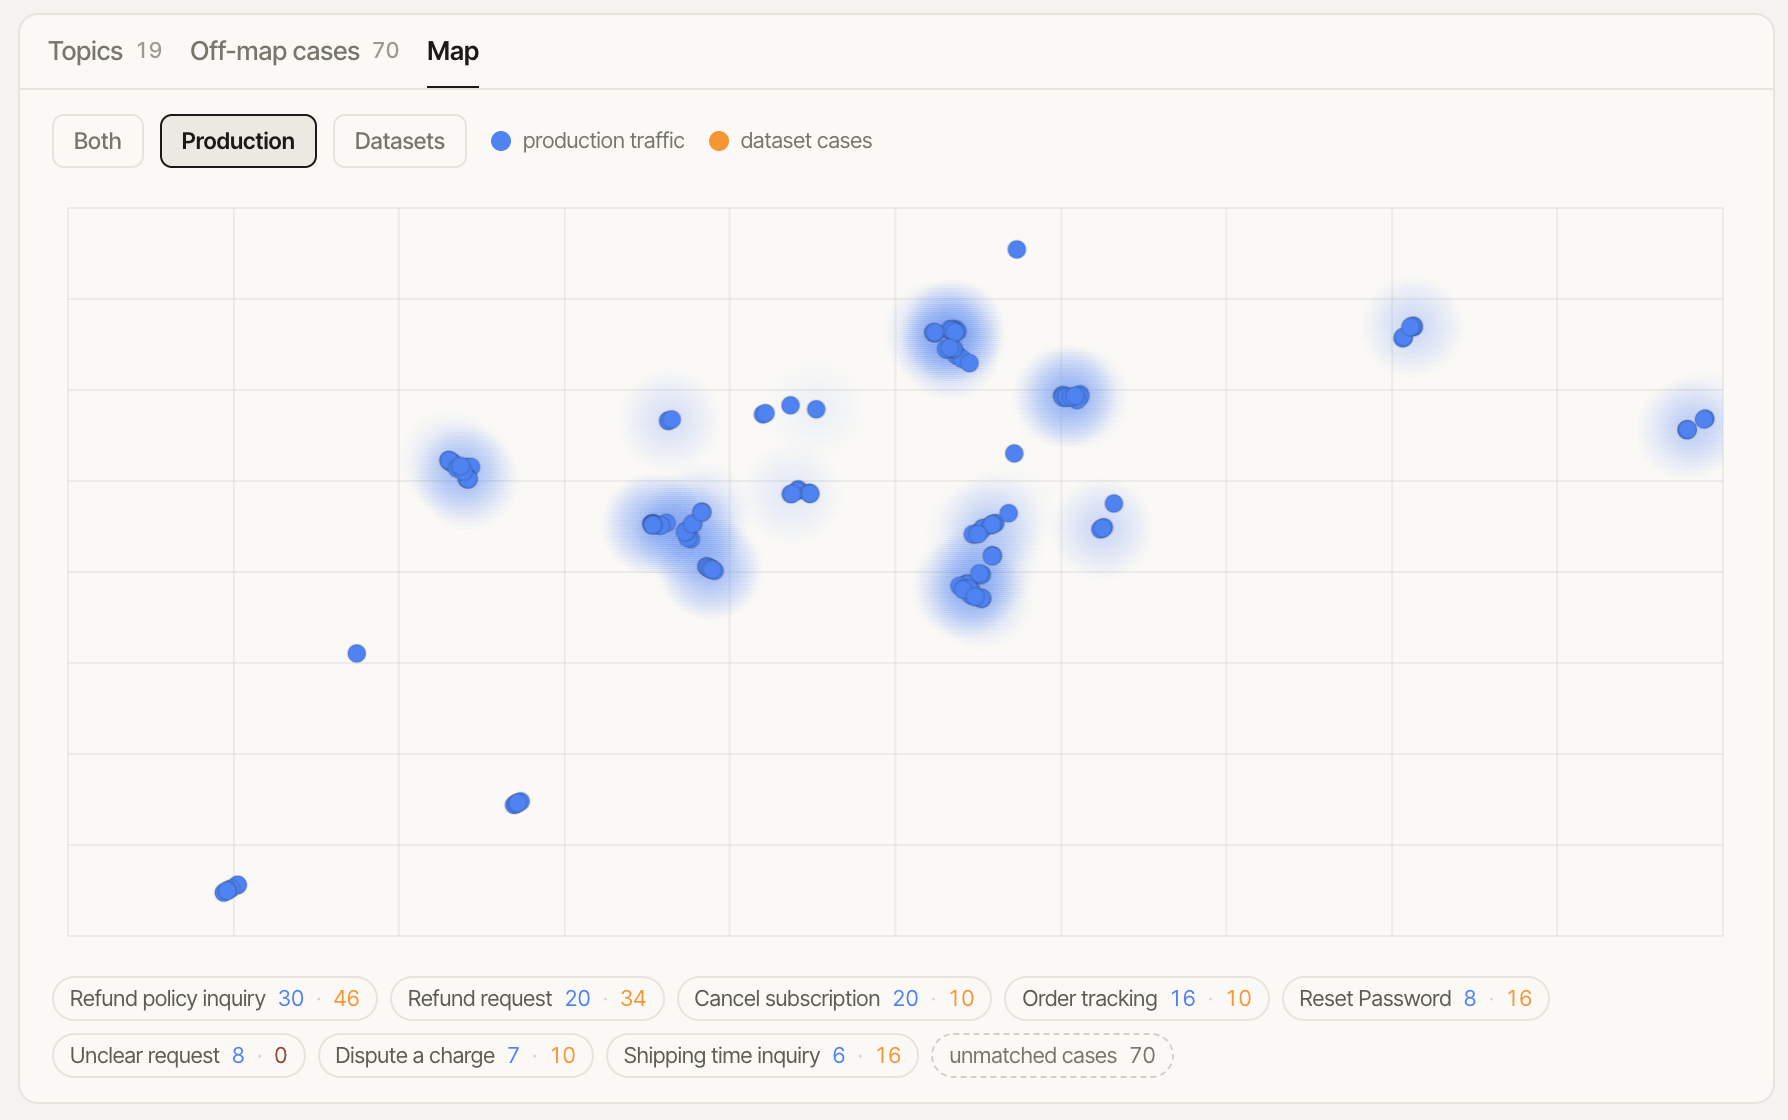
Source chip: Production. The blue cloud is the shape of real traffic in the selected date range, colored by classified topic in the legend.
3. Both together: coverage and the gap
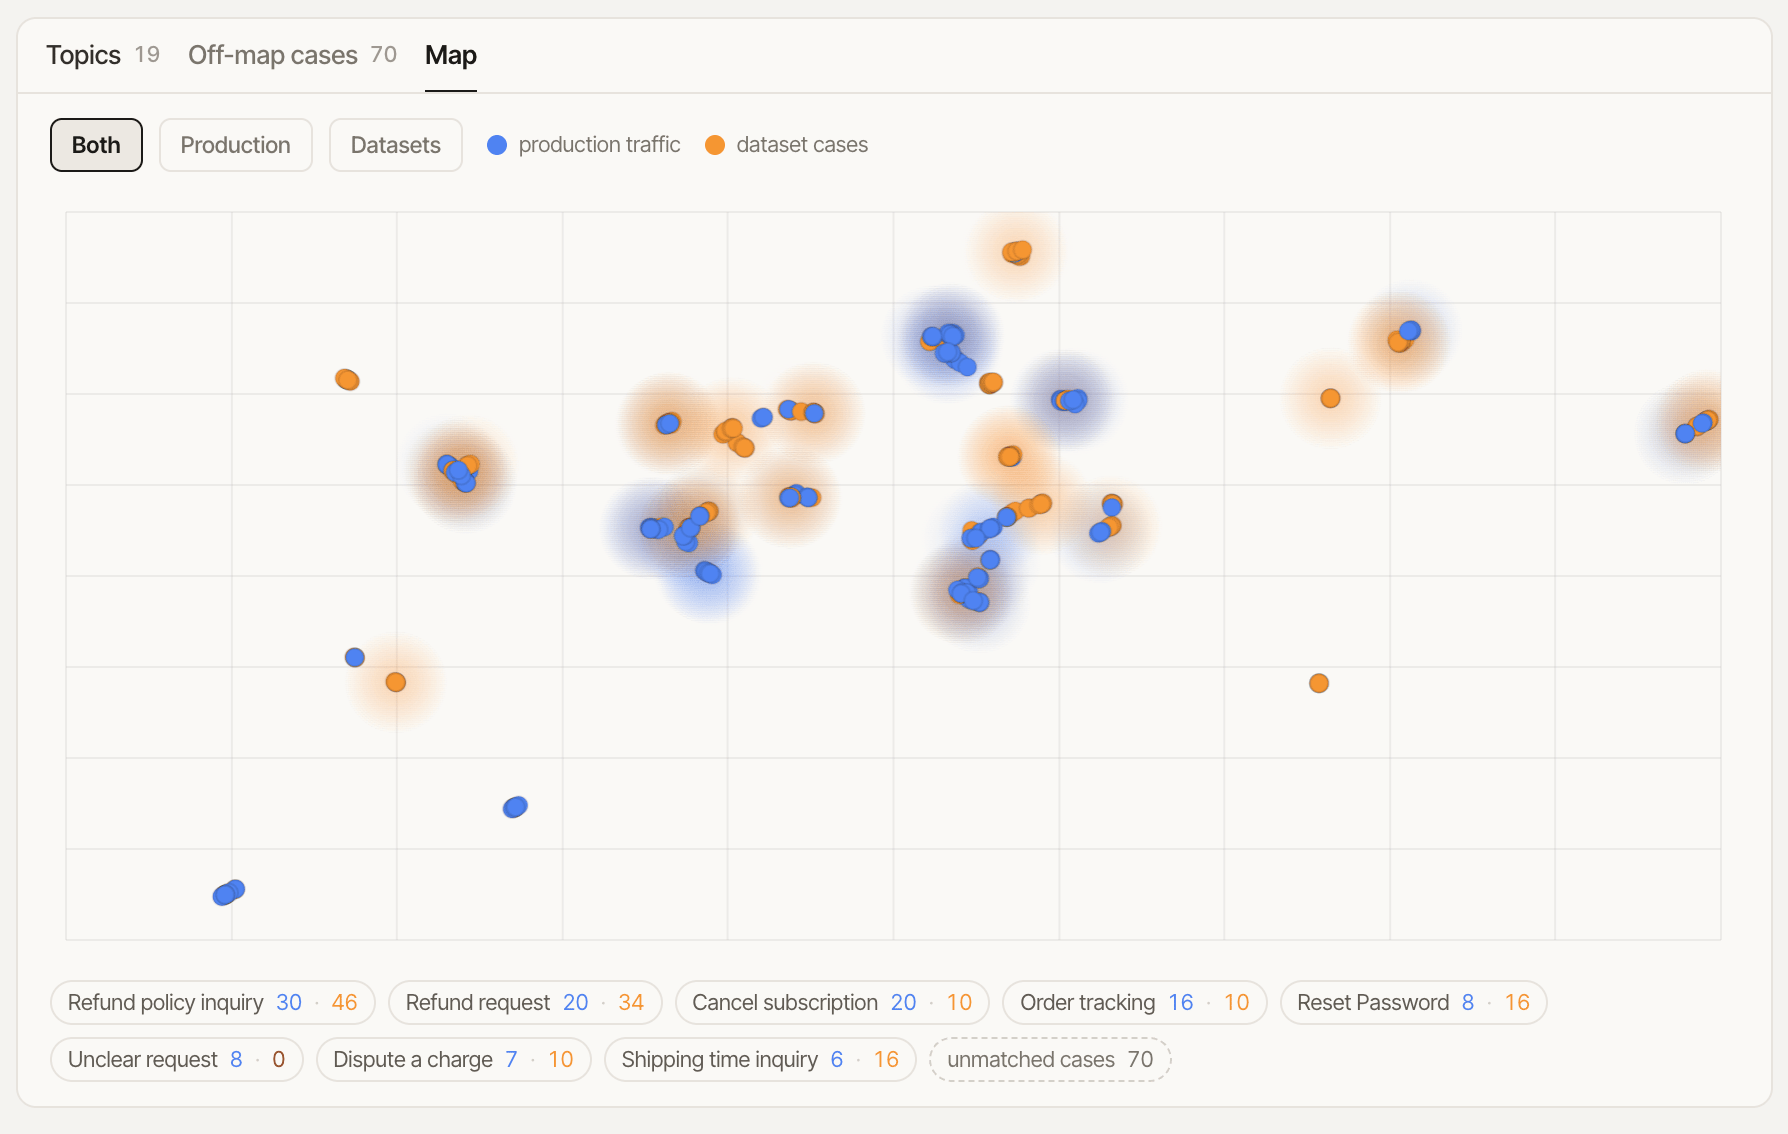
Source chip: Both. Where orange sits on blue the topic is tested; a blue region with no orange tint is the gap. The legend's production · dataset counts say the same thing in numbers.
- Blue and orange blend where dataset cases sit on production traffic: that topic is tested.
- A blue region with no orange tint is the gap: production asks it, nothing tests it. Visible without reading a number.
- Orange with no blue underneath is a test nobody needs: cases about questions production does not ask.
- The topic legend shows
production · datasetpoint counts per topic.34 · 0is an untested topic before you have read the chart at all. Hovering a topic spotlights its points and cloud while dimming everything else. - The map inherits the page’s date range and dataset filter. Cases or traces still warming show as an N still indexing chip rather than silently missing (traces classified before the question-space column existed backfill in bounded batches as the map is viewed).
The three headline numbers
The Topics tab turns the same join into numbers you can track over time.
A fourth card, Cases off the map, lists dataset cases matching no topic production asks:
candidates to retire. Each opens with its expected results and nearest topic, so retiring is a
read decision, not a guess.
Coverage is depth, not case count
A topic’s coverage is a facility-location value over the topic’s real traces: each production trace is scored against its nearest case, so near-duplicate cases add nothing and the number cannot be inflated by generating copies. A topic whose traces carry no embeddings falls back to case-count-against-target for that topic alone, and says so (“cases against target - no depth available”). The “covered” threshold is the same similarity bandaddCaseToDataset uses for dedupe.
Covered literally means the dataset would reject this query as a duplicate.
The table’s topic matching runs in interaction space (input+output against
query+expected), which is the right space for “is this behavior tested”. The map runs in
question space instead, because interaction space separates identical questions whenever the
actual answer differs from the expected one, which is exactly when a reader would call the
picture broken.
Working the gaps
The topics table ranks by priority = traffic exposed x (1 - coverage) x risk amplification. A covered topic is worth nothing to work on however busy, and a risky topic outranks a healthy one carrying several times its traffic. The Next up chips surface the top three. Selecting a topic opens its detail rail:- the four per-topic numbers (traffic with trace/session counts, cases against target, coverage with its basis, observed risk with its issue/negative split),
- Production traces in this topic: the newest real requests with the classifier’s verdict, so a gap is judged by reading what production actually asked. Each trace carries an Add test case button, the manual path for turning that one request into a case,
- Suggested action with one button: Generate N cases from traces creates candidate
cases from the topic’s own traces through the standard curation path (deduped, versioned,
expectedResultsdeliberately left for you to write). A generated case is a scaffold to review, never a fabricated assertion.
N · 0 count, switch to the Topics tab where the same topic
sits at the top of the priority queue, generate cases from its traces, write the expected
results, and re-open the map. The orange tint appearing over that region is the receipt.
The probe: “is this already tested?”
The probe card answers coverage for one specific query, or a pasted list (a launch spec, a support macro export) as a pre-launch gate. Verdicts distinguish a real gap (production asks this, nothing tests it) from untested and unasked (nothing tests it, but nobody asks, deliberately neutral, because writing that test is work nobody needs). While cases are still embedding, a negative verdict downgrades to warming rather than asserting a gap it cannot yet prove.Scoping and export
The date range (presets from 6 hours to 90 days, or a custom range capped at one year; the default is the past 30 days) and the dataset filter scope every number on the page, the map included. Export writes exactly the rows on screen as CSV; the filename is prefixedprovisional- when the numbers are still a floor (case embeddings indexing) or
approximate- when they are lexical.
API
GET /api/v1/insights/coverage?window=30d&datasetId=...: the full coverage result.GET /api/v1/insights/coverage/map: the coverage map (same scoping parameters; a separate route because the joint UMAP fit is heavier than the coverage sweep, so you only pay for it with the Map tab open). Returnspoints(x,y,source,topic,query, and the trace or case reference) plus per-topicproductionCount/datasetCount. Needs at least 10 embedded points across both sources; below that it returnsinsufficientData: truewith the reason.POST /api/v1/insights/topics/curatewith{ topic, datasetId, window?, limit? }: the “Generate N cases from traces” action (returns{ ok, added, duplicates, considered }).limitdefaults to 6 and is capped at 12; anything larger is a bulk import, which has its own surface.POST /api/v1/insights/probeand/probe/batch: the probe.
window (24h / 7d / 30d) or an explicit custom range as
from and to (epoch milliseconds, to > from, capped at one year), the same range override
every monitoring dashboard route takes. datasetId and datasetIds are interchangeable, each
accepted repeated or comma-separated.